-
Research
- Structure Search on Crystal Surfaces
- Quantitative Text Analysis with Large Language Models
- Computational Archival Science
- Analysis of Public Works Bidding Data
- Fast Nearest Neighbour Search
- Similarity Measure Design for Discrete Data Structures
- Development of Fast Feature Selection Algorithms
- User Behavior Estimation from Computer Logs
- Genetic Mutation Analysis of Influenza Viruses
- Time-Series Topic Extraction from Social Media
Research
My research areas are data mining and machine learning. The common thread is a single question: how do we enumerate discrete structures, and how do we compare them?
- Structure search on crystal surfaces (enumeration of discrete structures, SAT, Bayesian optimization)
- Quantitative text analysis with large language models
- Computational archival science
- Analysis of public works bidding data
- Fast nearest neighbour search and knowledge discovery from bipartite graphs
- Similarity measure design for discrete data structures
- Development of fast feature selection algorithms
- Analysis of operation logs and social media
They are ordered roughly by where the weight of my current work lies. But they share methods and questions, and none of them has an end date: what changes is the emphasis.
Structure Search on Crystal Surfaces
Modelling crystal growth requires an exhaustive account of the atomic configurations a crystal surface can take. This is an enumeration problem over discrete structures defined on an infinite plane, and at the same time a structure optimization problem: selecting the stable configurations out of an enormous candidate set.
I approach both from two directions:
- Validating constraints with SAT solvers. The local electron counting rule, an empirical criterion for surface stability, is formulated as a logical formula, and its validity is examined by satisfiability testing.
- Combining Bayesian optimization with first-principles calculation. Expensive density functional theory evaluations are sampled efficiently under Bayesian optimization, to search for stable configurations on GaN surfaces and in graphene-like BCN systems.
Structure search requires a way to measure how similar two candidates are — which is where the similarity design work below becomes a tool rather than an end.
Main Collaborative Research
- Yoshihiro Kangawa and Akira Kusaba, Research Institute for Applied Mechanics, Kyushu University: first-principles calculation, digital twins, and structure search by Bayesian optimization
- Takashi Horiyama, Saitama University; Takeaki Uno, National Institute of Informatics; Kouichi Hirata, Kyushu Institute of Technology: enumeration algorithms for discrete structures
Quantitative Text Analysis with Large Language Models
Literature and political science are full of judgements that are obvious to a human reader but hard to produce consistently at scale: records of parliamentary proceedings, election bulletins, classical Chinese texts, discourse on social media. I am using large language models as evaluators to bring quantitative analysis to such domains.
The difficulty is that an LLM’s output cannot be used directly as a measurement. Assessing its stability and bias, and combining it with established quantitative text analysis and clustering, is where the actual work lies.
Main Collaborative Research
- Naoto Nonaka, Faculty of Law, Gakushuin University: comparative analysis of Japanese, British and French parliamentary texts
- Takeaki Uno, National Institute of Informatics: topic structure extraction by micro-clustering
- Takako Hashimoto, Chiba University of Commerce: time-series analysis of social media discourse
Computational Archival Science
Archival description records not the material itself but the process of the activity that gave rise to it, set down as context. The international standards for it — EAD, EAC-CPF, and the newer RiC (Records in Contexts) — are all data with hierarchical or graph structure.
Treating these descriptions as discrete structures, I work on visualising fonds structure, extracting context structures, and comparing the structures of the standards themselves. It can equally be read as an application of the similarity design for trees and graphs that I worked on in my doctoral thesis.
The material is not only the standards themselves but also the data of record management as it is actually practised. Using the file registry of the Japanese central government, I analyse quantitatively how records are classified and how they are described.
An introductory textbook on RiC is available as open teaching material.
Analysis of Public Works Bidding Data
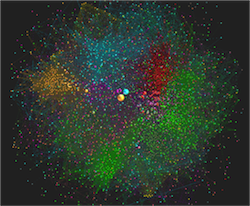
The bid rate is widely known as a criterion for judging appropriate competitive bidding versus bid-rigging. However, solving a regression problem with the bid rate as the objective variable does not necessarily allow for analyzing the appropriateness of competitive bidding.
In this research, I focus on the connections between companies participating in bidding and analyze the temporal changes in their structure and changes in company communities. The figure visualizes the connections between bidding companies of a local government as a network.
By extracting and analysing the relationships hidden in massive bidding data, I am developing new methods for bidding data analysis. In particular, I work on time-series network community extraction to find groups of companies that participate in the same bids exclusively.
Main Collaborative Research
- Kentaro Fukumoto, Graduate Schools for Law and Politics, The University of Tokyo: Joint collection and database creation of massive public works data from local governments.
-
Akihiro Yamamoto, Kyoto University:
Development of time-series community structure extraction algorithms using matrix decomposition
Fast Nearest Neighbour Search
Finding the data point closest to a query in a large database is a basic operation in search and machine learning. As dimensionality grows, exact search costs little less than brute force.
This work projects each data point onto a short bit string — a sketch — narrows the candidates by cheap sketch comparison, and only then computes exact distances. The design questions are how many bits a sketch should have, in what order sketches should be enumerated, and how many filtering stages to use. We have proposed conjunctive enumeration in order of Hamming distance, and two-stage filtering with short and long sketches.
Main Collaborative Research
- Kouichi Hirata, Kyushu Institute of Technology, with Takeshi Shinohara, Naoya Higuchi and Yasunobu Imamura
Similarity Measure Design for Discrete Data Structures
I design similarity measures for discrete data structures more complex than strings, such as tree structures, ordered structures, and graph structures. I investigate their theoretical properties and apply the results to data mining and machine learning.
Similarity and Distance Design
Tree structures play an important role in various algorithms and are used to represent syntactic trees, phylogenetic trees, and glycan structures in biology.
When two tree structures are given, how similar are these two structures? The metric (similarity or distance) to evaluate this degree is not unique.
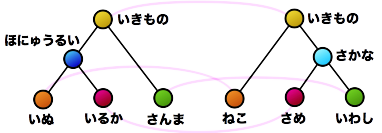
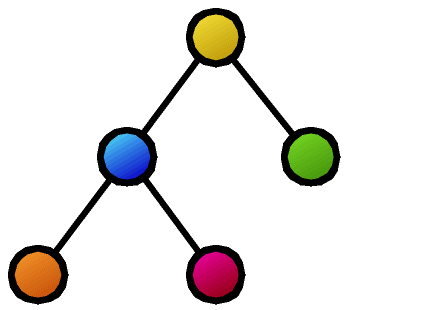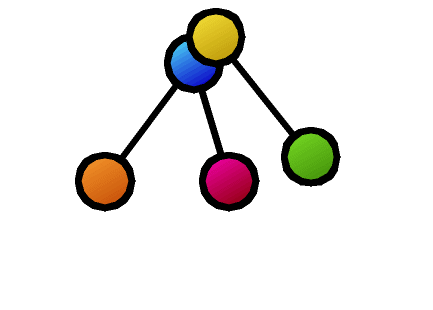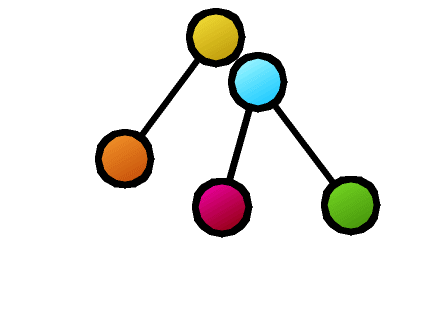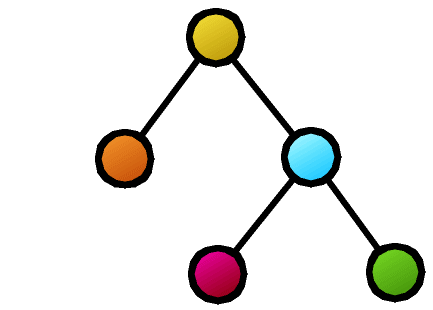
The coarsest evaluation method is to ask whether the two structures are perfectly identical (isomorphism testing). Efficient algorithms are known for tree isomorphism testing. However, the problem of evaluating how similar the structures are while tolerating some mismatches is not so simple because:
- Various definitions of similarity and distance can be considered
- In general, computation is very difficult (for example, the tree edit distance calculation problem for unordered trees (of a certain class) is NP-complete)
The widely used edit distance is defined by the minimum cost of edit operations to transform one structure into another. In this research, I organized various tree edit distance algorithms and similarity concepts that had been developed without clear criteria, clarifying their interrelationships.
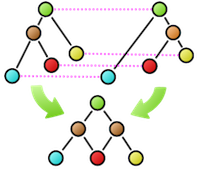
Furthermore, many basic properties related to tree comparison are surprisingly unknown. For example, as shown in the figure, suppose that as a result of calculating the similarity between two trees, the nodes connected by dashed lines correspond to each other. Is it possible to create a new composite tree (supertree) by overlapping these corresponding nodes while maintaining the hierarchical relationships of each tree? In this example, the red nodes become confluent points, making it impossible to maintain the tree structure. The necessary and sufficient conditions for taking node correspondences such that the composite becomes a tree structure after composition were first clarified by our research.
I approach the design of similarity and distance measures from mainly two perspectives:
- Optimization Problems
- Design similarity/distance measures as maximization of common parts (maximum common subtree problem) or minimization of mismatched parts (tree edit distance problem). The advantage is that constructively, which parts are similar can be understood from the calculation result (represented as lines connecting the two tree structures in the figure).
- Enumeration Problems
- Counting of common substructures. The advantages of calculating similarity/distance as an enumeration problem are that local similarities can be captured, that constructive calculation is not necessarily required, and that it can be immediately applied to classification learning of tree structures (tree kernel design in machine learning).
These fundamental research results have been applied to classification learning of cancer-derived glycan structures and analysis of temporal community hierarchical structures.
Main Collaborative Research
-
Kilho Shin, Gakushuin University:
- Generalization and theoretical systematization of various tree edit distances, application to tree kernel design
- Theory of kernel design for discrete data structures
- Kouichi Hirata, Kyushu Institute of Technology: Class hierarchy of tree edit distance algorithms and correspondence with computational complexity
- Akihiro Yamamoto, Kyoto University: Tree edit distance algorithms and development of new tree distance metrics
-
Eisaku Maeda, Tokyo Denki University:
- Ise pattern digital archive (joint research with Art Research Center, Ritsumeikan University)
Development of Fast Feature Selection Algorithms
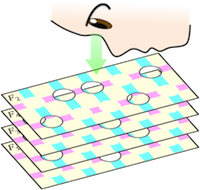
Feature selection is the problem of extracting only the necessary attributes from data with numerous attributes for a specific purpose. It is an important fundamental problem in data mining and machine learning.
In this research, I focus on the feature selection problem for categorical data, which includes interesting subproblems connecting discrete and continuous domains. I work on analyzing the theoretical properties of CWC, which is one of the most high-performing existing algorithms, improving the algorithm, and applying it. CWC formulates the feature selection problem as a kind of set covering problem and extracts features using a greedy method (the figure shows an image of the algorithm).
Despite using a very simple evaluation metric to decide whether to keep features, CWC has been shown experimentally to perform very well on various benchmarks. I work on analysis that would support this high performance theoretically.
I am also applying this algorithm not only as a preprocessing step for machine learning but also for rapid topic word extraction from massive documents.
Developed Software
- sCWC: A high-speed feature selector that supports massive sparse data. Implemented in Scala.
Main Collaborative Research
-
Kilho Shin, Gakushuin University:
CWC, the feature selection algorithm this work builds on, was proposed by
Prof. Shin in 2011.
User Behavior Estimation from Computer Logs
This work estimated user behaviour from computer log information, particularly active window transition data.
Assuming that window transitions are generated by underlying tasks, the logs were segmented with hidden Markov models. From these abstracted task units a state transition diagram was built for each user; treating those diagrams as graph structures, users with similar work patterns were clustered using graph kernels and kernel principal component analysis. The idea is simple, but it yielded interpretable results that corresponded to actual business operations. Statistical features of window switching were also used to determine work attendance status.
Joint work with the late Hiroshi Yasuda, former President of Tokyo Denki
University.
Genetic Mutation Analysis of Influenza Viruses
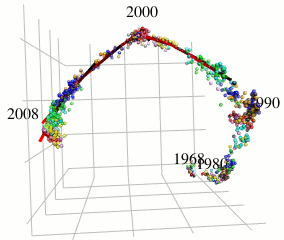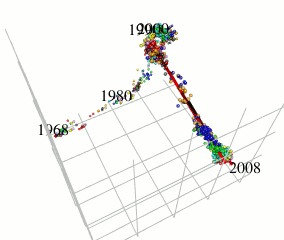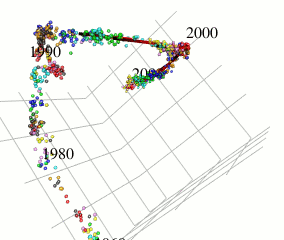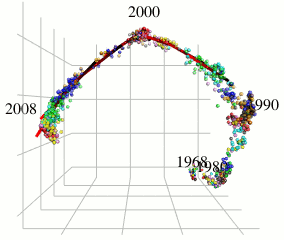
This work looked at type A influenza viruses, which cause global epidemics, and aimed to construct a continuous mutation model of antigens from amino acid sequence data. It took a different approach from the research on mutation prediction and co-mutation pattern extraction by Kimihito Ito and colleagues at the Research Center for Zoonosis Control, Hokkaido University.
Existing research predicts mutations by observing changes in the hemagglutinin gene’s amino acid sequence within the Hamming distance space. In contrast, this research extracts only the components of influenza virus evolution direction using locally sparse principal component analysis by embedding the amino acid symbol space into Euclidean distance space (with low distortion) while preserving the properties of the Hamming distance space (see figure). This improved on the prediction performance of existing methods.
The problem settings and research themes came from Kimihito Ito, Research Center for Zoonosis Control, Hokkaido University.
Time-Series Topic Extraction from Social Media
This work extracted the evolution of user needs from time-series data such as Twitter, blogs, and review comments on shopping sites. Besides topic extraction methods from natural language processing, it used hierarchical community extraction over networks combined with tree edit distance, among other methods.
Joint work with Takako Hashimoto, Chiba University of Commerce, including a time-series analysis of how the needs of disaster victims changed after the Great East Japan Earthquake. This line of work continues in Quantitative Text Analysis with Large Language Models.